mist and mistv2 default to MP3, while coda and mistv3 default to WAV. Use --format to override.
Required flags
Optional flags
Coda flags
The CLI rejects these flags formist, mistv2, and mistv3.
mist/mistv2/mistv3 flags
The CLI rejects these flags forcoda.
mist/mistv2 flags
Onlymist and mistv2 support these flags, so the CLI rejects them for mistv3.
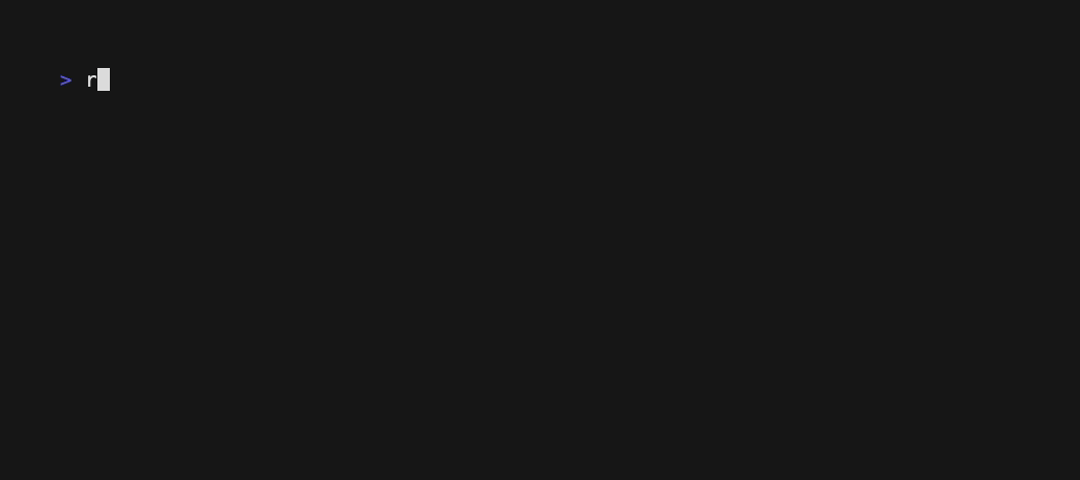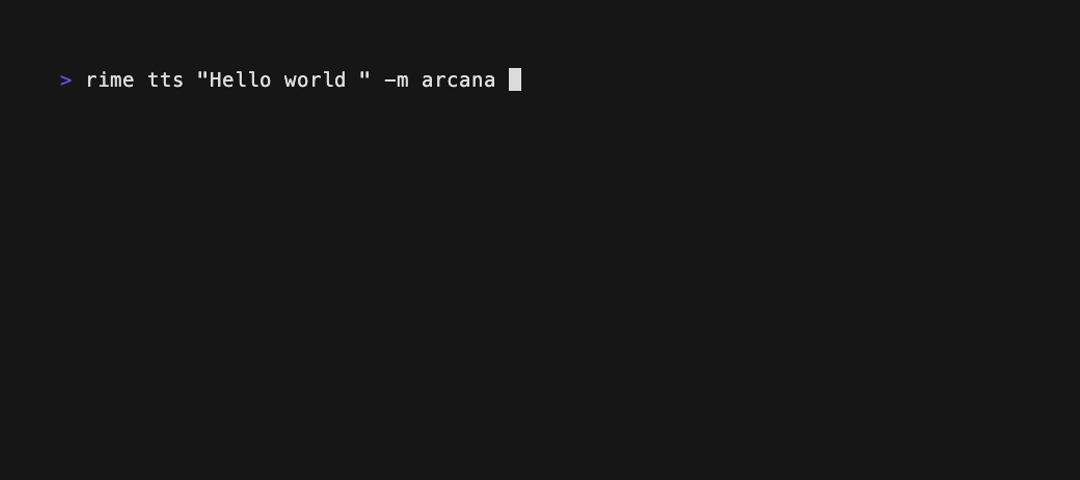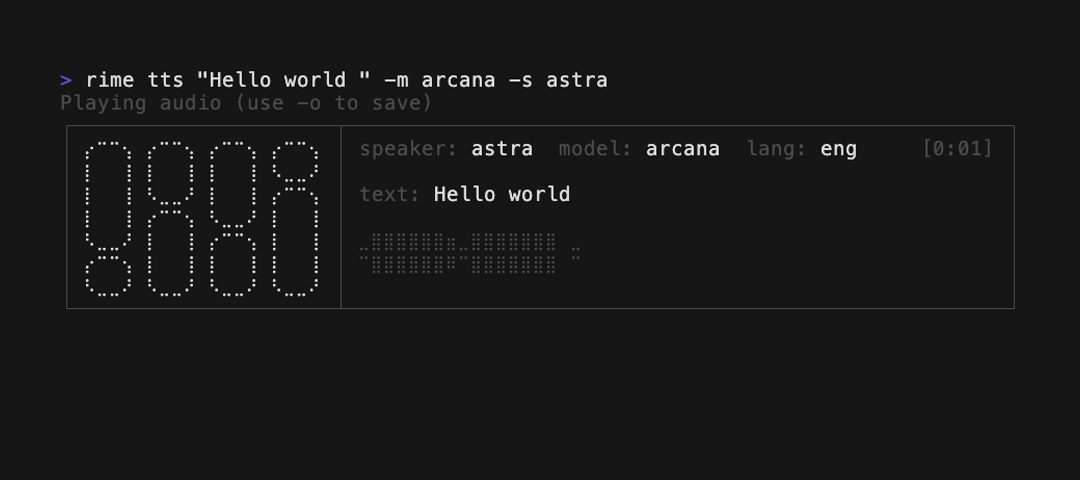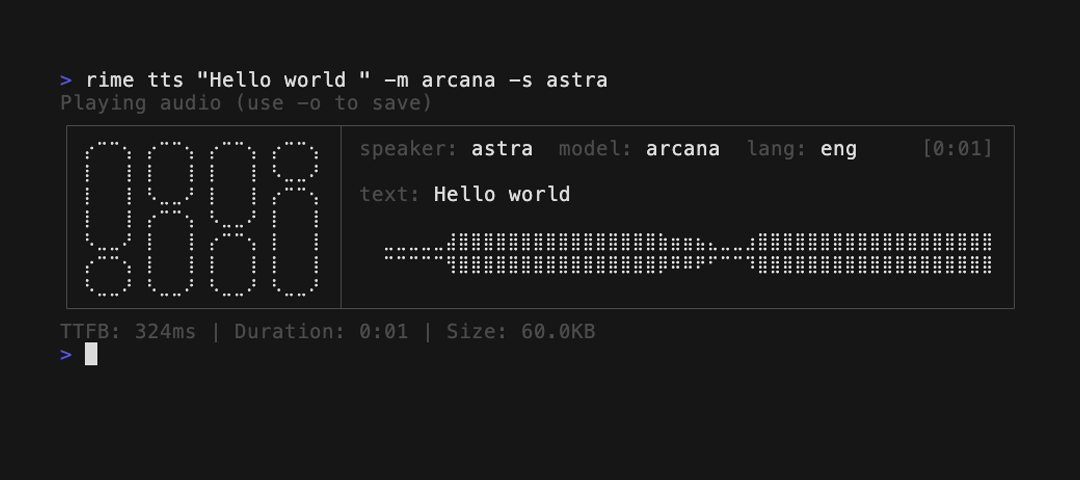
Examples
Language
Omit--lang and the model synthesizes in its own language, which is what you
want for a voice that speaks one language. Pass a BCP 47 tag to be explicit, and
choose a voice that speaks that language: astra is an English voice, so the
Spanish example above uses brisa.
The CLI does not check --lang: it sends the value as given, and the API
rejects a tag the model cannot serve. See Languages
for what each model supports.